QWEN3-CODER-NEXT vs Qwen 3.8-27B Open Weights LLM Models on a Threadripper 64GB AI Workstation with 4 RTX-3060 12GB (48GB Combined VRAM)
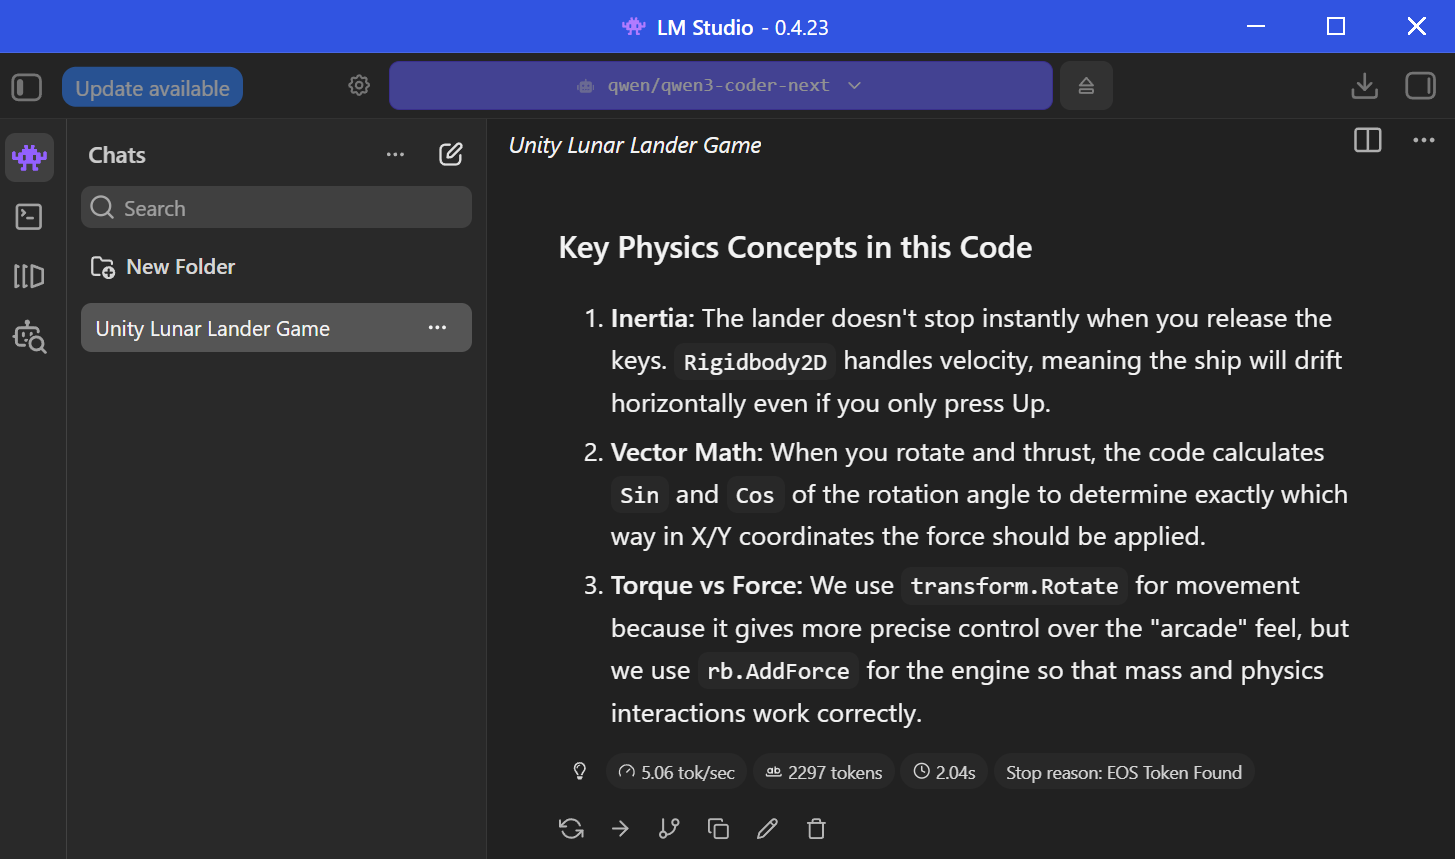
Earlier this summer, I tried running the QWEN3-CODER-NEXT Open Weights LLM Model locally on one of my Threadripper 64GB AI Workstations with 4 RTX-3060 12GB using layers across my 48GB of combined VRAM. With QWEN3-CODER-NEXT, I was able to replicate my original Lunar Lander game in Unity C# but it was very slow at 5.06 tokens / sec. That is fast enough for offline agentic coding work but too slow for vide coding with chat.
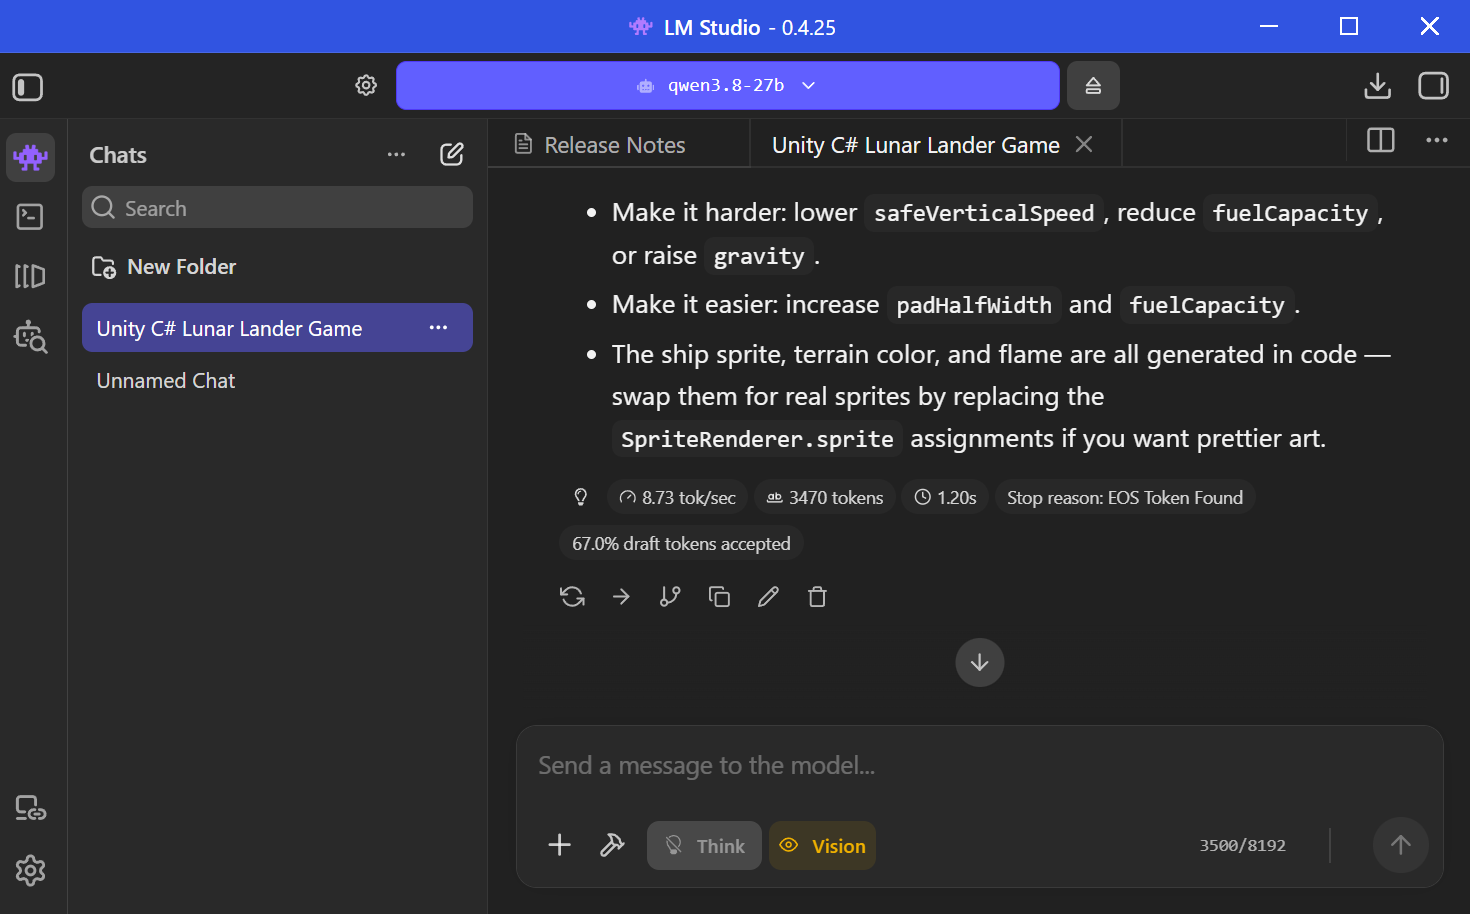
The newer Qwen3.8-27B model released on August 14, 2026 fits a little better in my 48GB of VRAM and got 8.73 tokens/sec. It is a little bit better at Unity C# coding if you feed it the Unity documentation as well. It also supports Vision so I can also provide it screenshots of the Unity Editor screen too.
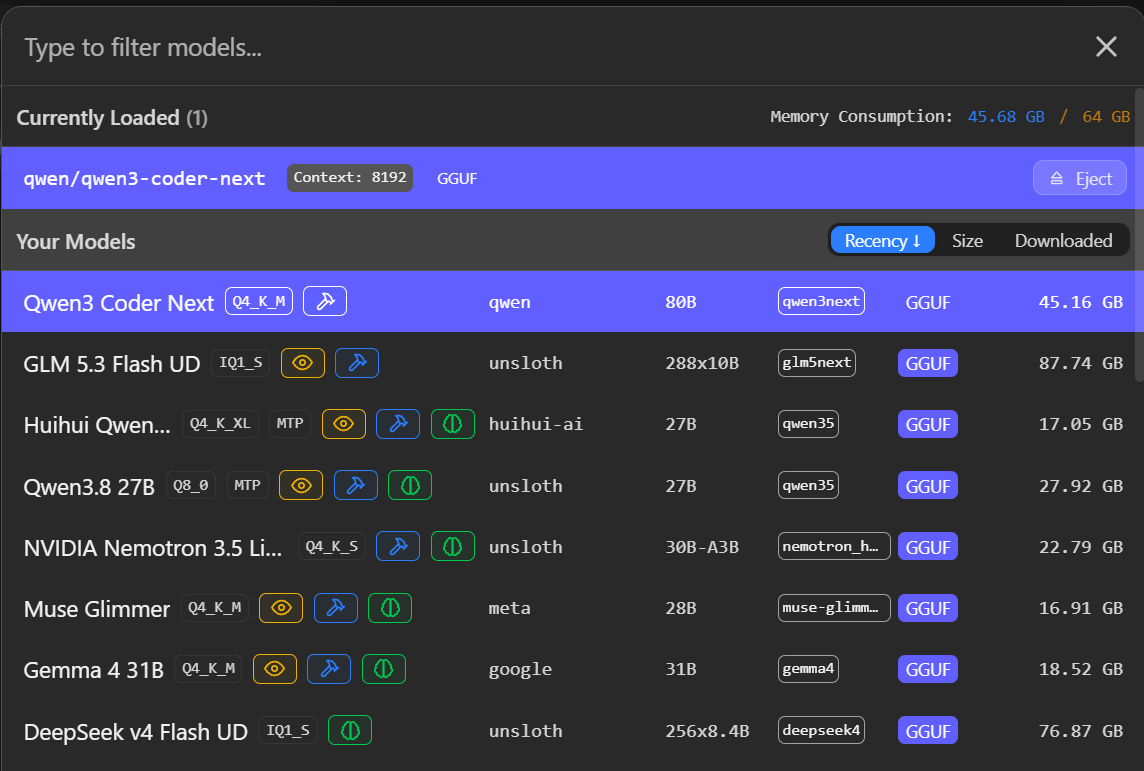
I will continue working through more local models which will layer comfortably across my 48GB of VRAM and see how they each do with Unity C# coding.
Hopefully, someday, I will find one that will perform as well as Anthropic’s last generation of cloud-based models. It would be really nice if OpenAI, Anthropic or Grok released some of their previous generation of closed models as local Open Weights highly quantized models for the Academic community and students to use on consumer-based GPUs.


