Most people look at four RTX 3060s with 12GB of VRAM each and see a budget build. I looked at it and saw something else: the exact hardware configuration  that the current generation of compressed, sparse, speculative models was designed around.

Here’s  my argument.  With quad Multi-GPU systems, the PCI has been the bottleneck. Each of my cards moves data to the others at roughly 25GBs per second. A single RTX-3090 moves far more internally. So any model that streams its full weight matrix across the bus every single token is dead on arrival. That’s what killed the Quad-3060 experiments back in in 2024 — people were loading four-bit 70B parameter models, which meant 35GB of weight traffic per step. Four  RTX-3060 cards barely beat one RTX-3090. The PCI topology lost.

In 2026, two things have changed. First, two-bit quantization. Nemotron 3.5 Bolt at IQ2 is a 22GB file. You’re not streaming 35GB anymore. Second, mixture-of-experts. Bolt activates only a slice of its experts per token — the active weight footprint drops to 2-4GBs which PCIe can actually feed without breaking a sweat. Third, speculative decoding with the LiLiCorr drafter: most tokens get generated by a tiny model that never touches the big one. Your cards spend their bandwidth on KV cache and occasional full passes, not constant weight streaming.

Then there’s context. 256K tokens at eight-bit KV cache is about 16GB on its own. No single 12GB card holds that stack. Four video cards pooling memory is the only consumer path to it. My Threadripper AI rig isn’t four small machines pretending to be one big one — it’s one memory pool that happens to be built from four RTX-3060 cards.

And this isn’t a one-off. NVIDIA’s compression recipe — take a parent model, distill it to two-bit, ship it with a drafter — is repeating every cycle. Super VL to Bolt, Bolt E4B dropping this week at 4GB. Diffusion models with open weights are coming. Every memory crunch pushes AI labs toward exactly this class: sparse, quantized, speculative. Abundant memory via multi-gpus, modest bandwidth, software trading compute for VRAM capacity.

Their Super and Lightning models ship with native multi-token prediction heads and NVFP4 quantization — same compress-then-quantize philosophy, just aimed at bigger hardware.   They’re taking something big, compressing the architecture, quantizing hard, and bolting on a speed layer. That’s the whole game now, and my four RTX-3060 cards are the ideal testbed for these new mid-range models.

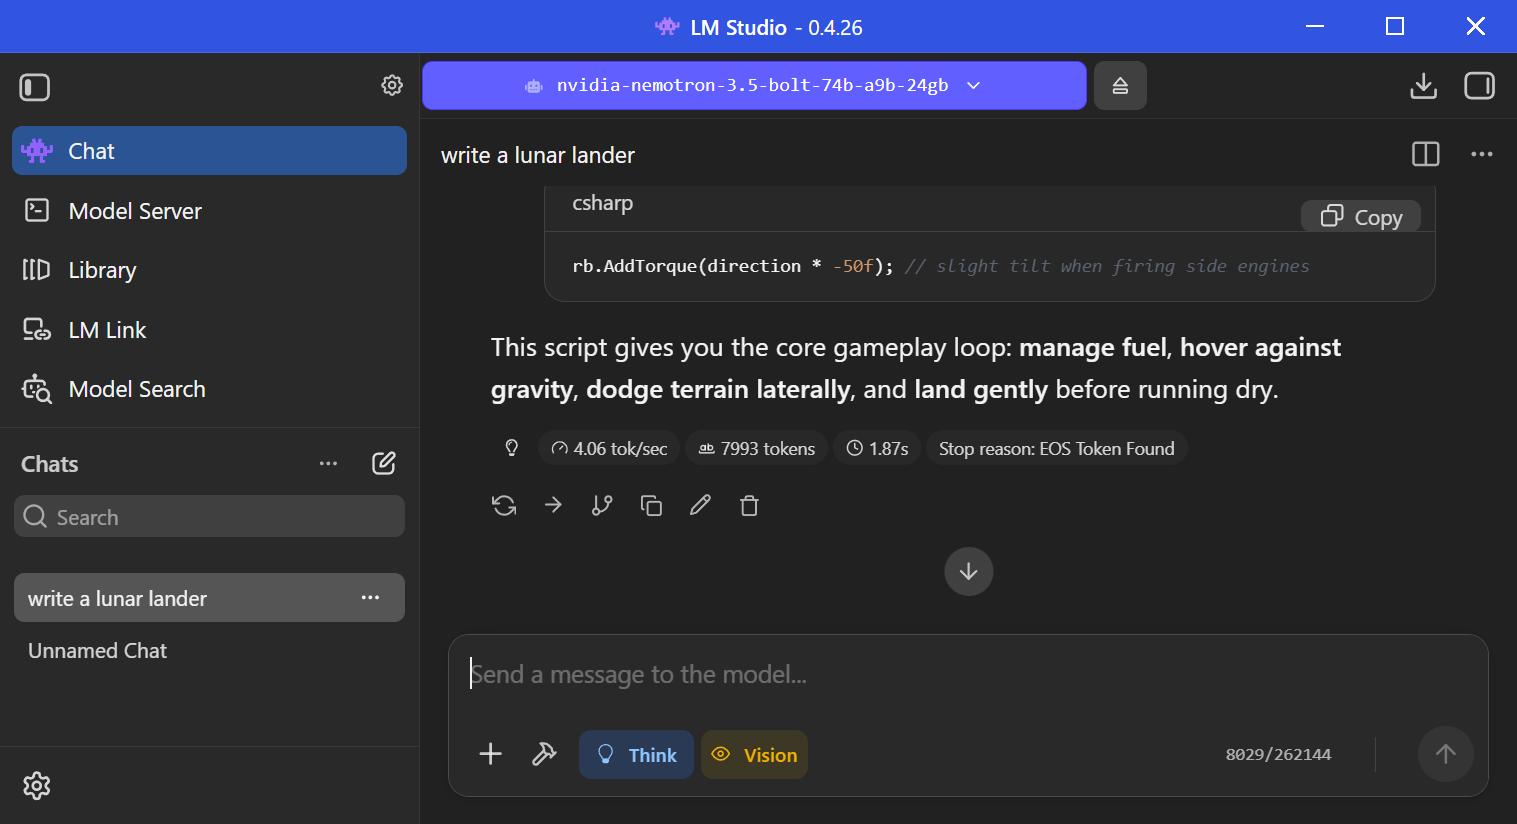
With my standard Lunar Lander Game test, i was able to get 4 tok/sec with a large 128MB Context Window.    I’ll do some more testing in the future with LiLiCorr drafter turned on to see if I can speed up the this sparse, quantized, speculative local model from NVIDIA.

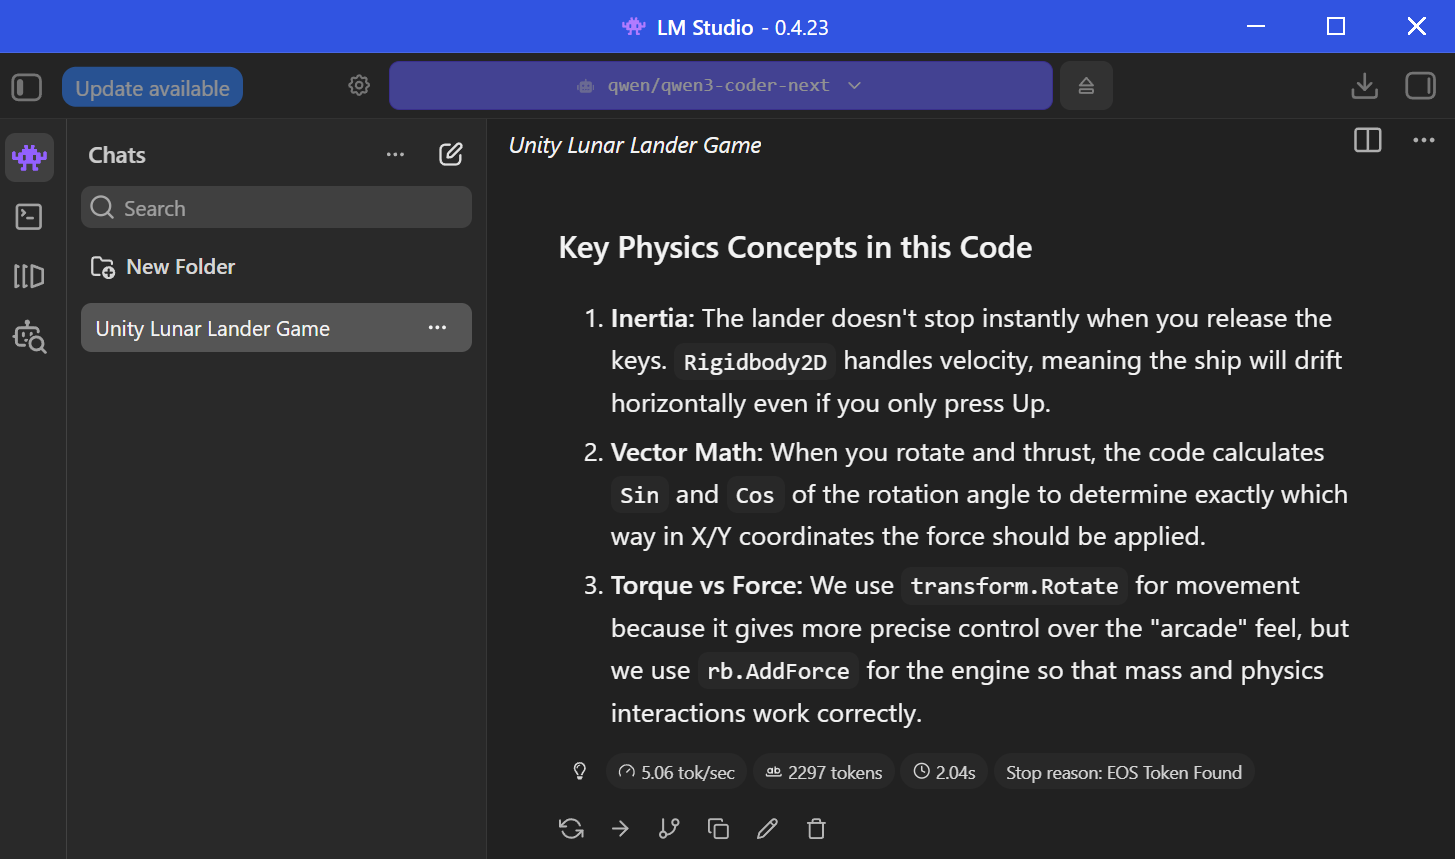
Earlier this summer, I tried running the QWEN3-CODER-NEXT Open Weights LLM Model locally on one of my Threadripper 64GB AI Workstations with 4 RTX-3060 12GB using layers across my 48GB of combined VRAM. With QWEN3-CODER-NEXT, I was able to replicate my original Lunar Lander game in Unity C# but it was very slow at 5.06 tokens / sec.  That is fast enough for offline agentic coding work but too slow for vide coding with chat.

The newer Qwen3.8-27B model released on August 14, 2026 fits a little better in my 48GB of VRAM and got 8.73 tokens/sec.  It is a little bit better at Unity C# coding if you feed it the Unity documentation as well.  It also supports Vision so I can also provide it screenshots of the Unity Editor screen too.

I will continue working through more local models which will layer comfortably across my 48GB of VRAM and see how they each do with Unity C# coding.

Hopefully, someday, I will find one that will perform as well as Anthropic’s last generation of cloud-based models for agentic coding.  It would be really nice if OpenAI, Anthropic or Grok released some of their previous generation of models as local Open Weights highly quantized models for the Academic community and students to use on consumer-based GPUs.


During my Summer break from teaching at Northwest University, I upgraded my home AI workstations with more memory to run larger local Open Source and Open Weights 48GB LLM Models using CrewAI.  I also needed to bake lighting in some of my very large Unity 3D open world environments (e.g. Exodus Vigil, Castle Quest) using a lot more Multi-GPU VRAM.

CrewAI is an open-source Python framework for building teams of AI agents that collaborate on a job, instead of stuffing everything into one giant prompt. You define people-like roles (“researcher,” “writer,” “reviewer”, “developer”, “tester”), give each a goal and tools, then CrewAI handles handoffs, context passing, and the process that runs them. CrewAI is not an LLM itself. It is the orchestration layer. The actual thinking and reasoning is done by whatever model you point it at.

I upgraded a couple of Azrock Taichi 399 AMD Threadripper AI Workstations with Quad Multi-GPU Gigabyte RTX-3060 12GB VRAM video cards with a total of 48GB VRAM in each system with 64GB of DDR4 system RAM.  This allowed me to run multiple Crew AI Agents on each system working simultaneously together on several projects that I was working on.  This allowed me to start baking my larger Unity 3D open world scenes using Bakery with multi-GPU light baking.   Now I can light bake very large levels and render larger and longer cutscene videos faster.

The largest models that fit comfortably in the Quad RTX-3060 with 48GB of VRAM are ~70B parameter model quantized to Q4_K_M or Q5_K_M.  That is roughly 35–45 GB total VRAM needed after overhead.  With 4 × 12GB = 48 GB total VRAM, I can run up to a 70B–90B model in Q4/Q5, or a smaller dense model like a good 34B–70B at higher quantization for better quality output.

The Azrock Taichi x399 Threadripper systems provide plenty of PCIe lanes for good multi-GPU scaling.  12GB per card is proving excellent for layer offloading using Ollama or LM Studio.  These factors have increased my local AI model sizing over my single GPU RTX-3080 10GB VRAM Alienware R11 system.  This is proving to be a very economical and capable local AI system for the AI work I want to do over my summer break.  So far, the multi-GPU systems are proving excellent for running large models for offline chatting, coding assistance, and light fine-tuning for coding.

I plan to test the following AI Models locally on it:

Rank
Model (Size)
Best For
Why It’s Good for Game Dev
VRAM Needed (Q4/Q5)
1
Llama 3.3 70B or Llama 4 70B
All-around best
Excellent coding, reasoning, long context
~40–45 GB
2
Qwen 2.5 Coder 32B
Programming & Scripting
Top-tier code generation (C#, C++, Blueprints, HLSL)
~20–25 GB
3
DeepSeek R1 or DeepSeek Coder V2 236B (MoE)
Complex coding & architecture
Outstanding for game systems & optimization
~35–45 GB
4
Command R+ (104B)
Creative writing & game design
Strong narrative, quests, dialogue, world-building
~45–50 GB
5
Mistral Large or Mixtral 8x22B
Balanced creative + technical
Good all-rounder for Unity/Unreal
~30–40 GB
For Unity development (C# focus):
  • Primary: Qwen 2.5 Coder 32B or Llama 3.3 70B
  • Great for Unity-specific tasks: Editor scripts, Addressables, DOTS/ECS, Shader Graph, UI Toolkit.
For Unreal Engine (C++ + Blueprints):
  • Primary: Llama 3.3/4 70B or DeepSeek Coder
  • Good for Unreal-specific: Niagara, Behavior Trees, GAS (Gameplay Ability System), Slate/UI, C++ performance optimization.

In case you are curious, here are the hardware components that make up my two Azrock Taichi 399 AMD Threadripper AI workstations:


I’ll follow up with another post at the end of summer to let you know how my local AI co-development went using these two AMD Threadripper Quad RTX-3060 48GB VRAM workstations and how many tokens/sec I got using each model.


Back in late March, I figured out how to install OpenClaw on my Windows 11 PC “securely” with the new NVIDIA NemoClaw.  NemoClaw provides OpenClaw an extra level of security and privacy so it can run more securely on your PC.  Currently it is still in early alpha!  I started with the Early Preview version and it is currently on Alpha v.0.0.17

NemoClaw does not run natively on Windows. The best (and most secure) method is to install it inside WSL2 (Ubuntu) with Docker Desktop. This setup game me a strong sandbox isolation while allowing my RTX 3080 to accelerate the local models.

Here are some screenshots of the secure PowerShell-first installation for NemoClaw + OpenClaw on my Windows 11 with an NVIDIA RTX GPU.

Installing GLM 4.7 Flash using Ollama:
I’ll let you know how it works out after they eliminate all of the early alpha bugs I ran into.  Don’t use it this in production.  I expect the production version will be much more stable when it releases later this year. I’ll let you know when that happens.  In the meantime, I will be testing Microsoft Execution Containers (MXC) to see if it is more stable and secure for running OpenClaw.

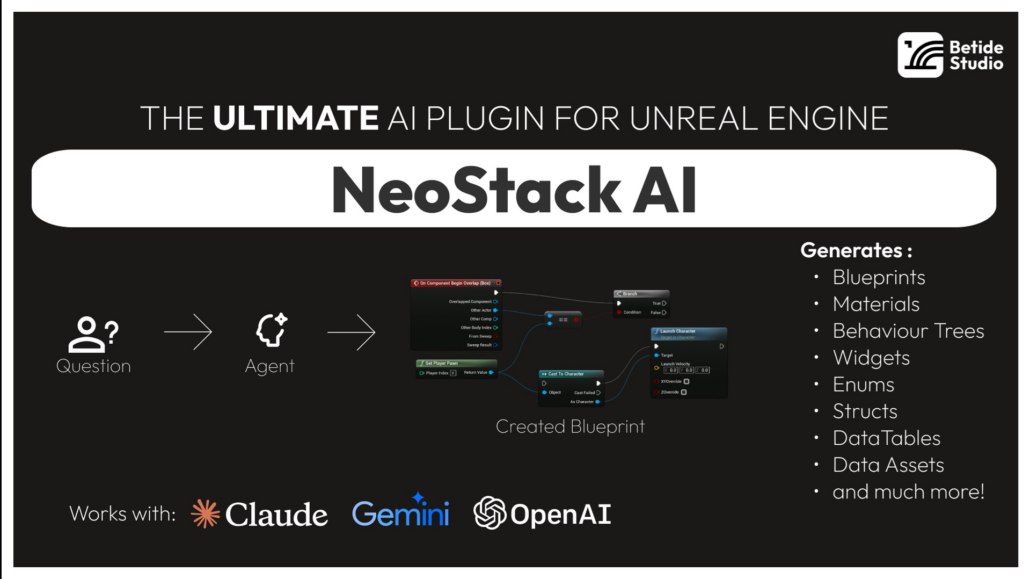
Back in February I started testing the NeoStack AI Plugin by BETIDE STUDIO for AI assisted Unreal Engine game development.   The NeoStack AI plugin is still in Beta, and I am currently testing the latest beta version (v1.0.66).

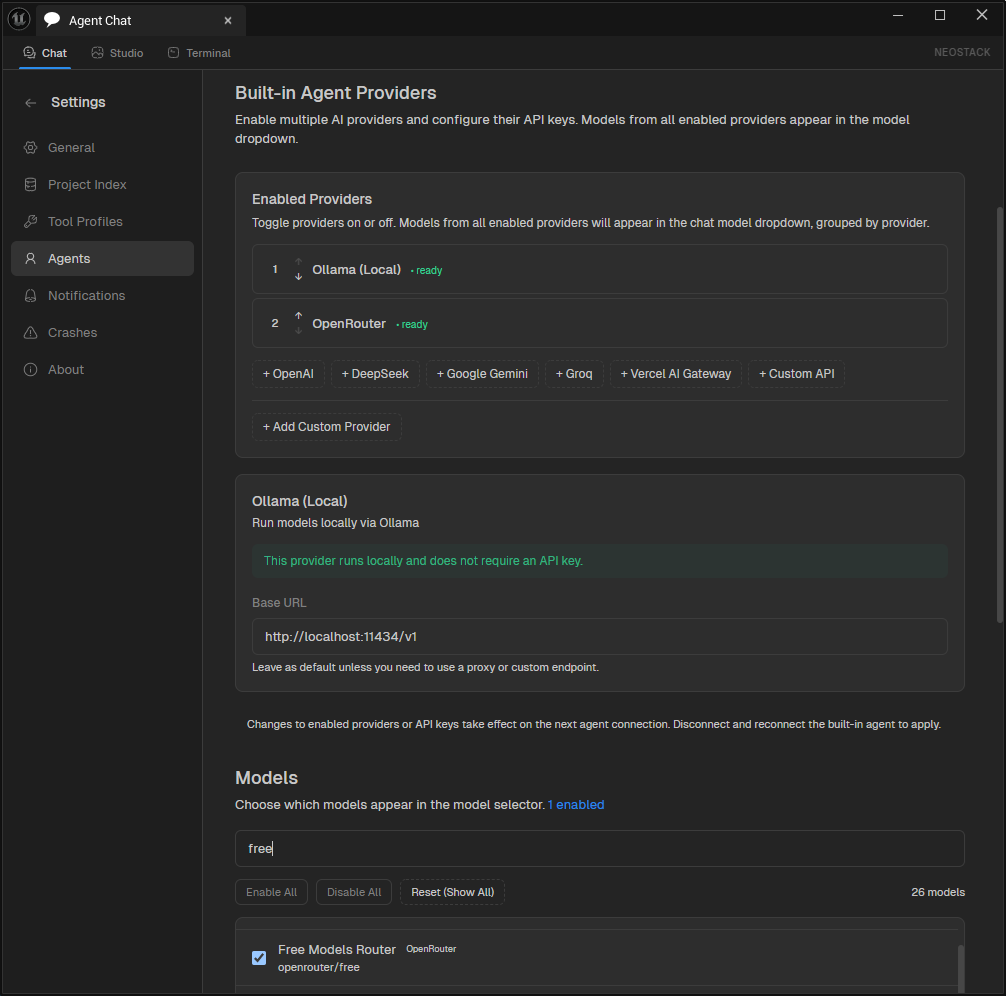
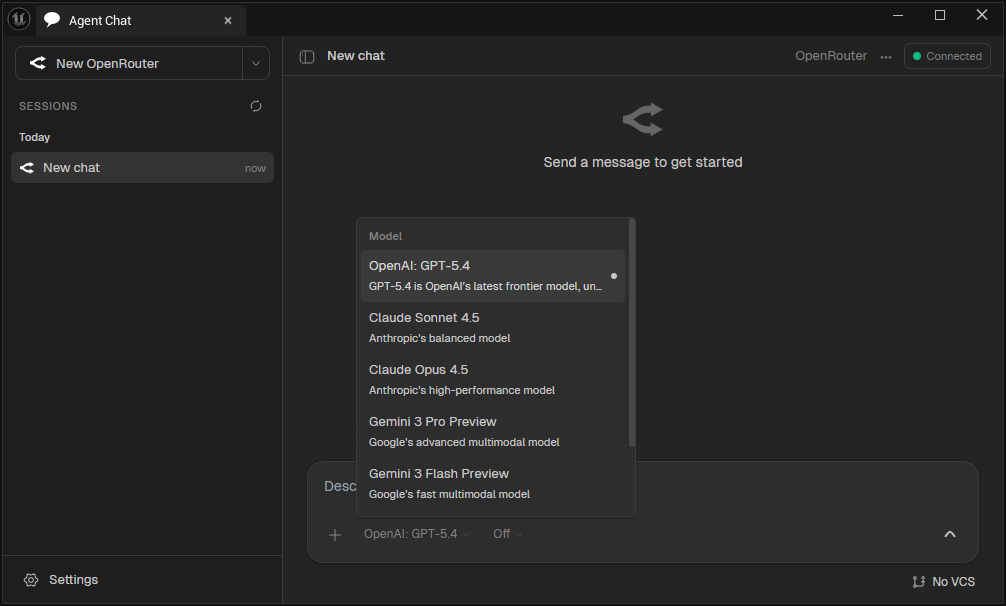
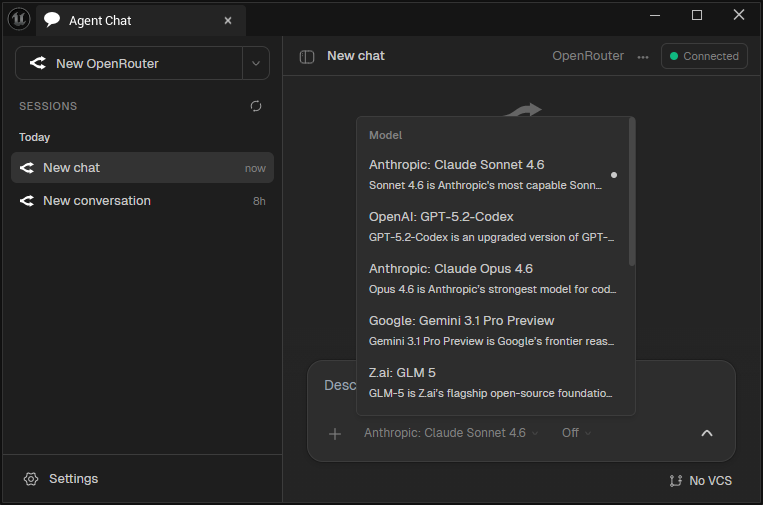
In addition to using OpenRouter to run free LLM models, NeoStack AI recently added the capability to run my free local LLM models via Ollama running on my GeForce RTX-3080.

I am really excited to use their new Ollama Local LLM model capability so I can take advantage of the free processing power of my offline NVIDIA GeForce RTX-3080 Graphics card.

As a reminder, the key features of the NeoStack AI are:

  • Multi-Agent Support – Connect to Claude Code, Gemini CLI, or OpenRouter
  • Native Editor UI – Slate-based chat window with streaming responses
  • Asset Generation – Create Blueprints, Materials, Behavior Trees, Data Tables and more
  • Context Attachments – Attach Blueprint nodes or assets to your prompts
  • Project Indexing – Automatic project indexing for context-aware suggestions

I’ll continue to keep you update on both my cloud and local LLM testing with NeoStack AI for Unreal Engine.


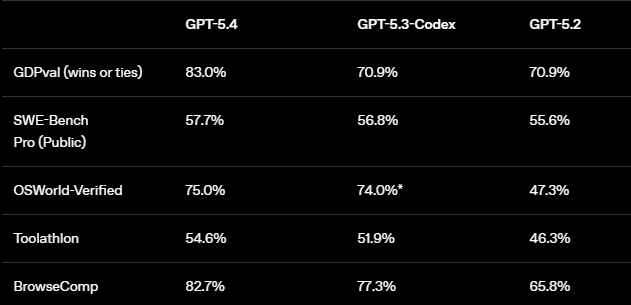
On March 5th, 2026, OpenAI released GPT-5.4  GPT-5.4 brings together the best of their “recent advances in reasoning, coding, and agentic workflows into a single frontier model”. OpenAI said that GPT-5.4 “incorporates the industry-leading coding capabilities of GPT‑5.3‑Codex⁠ while improving how the model works across tools, software environments, and professional tasks involving spreadsheets, presentations, and documents.”  GPT 5.3 Coden is great for agentic coding and combining it with GPT-5.4 helps you get real work done accurately, effectively, and efficiently.

OpenAI shared the following benchmarks comparing 5.4 to 5.3 Codex and GPT 5.2 in their announcement:


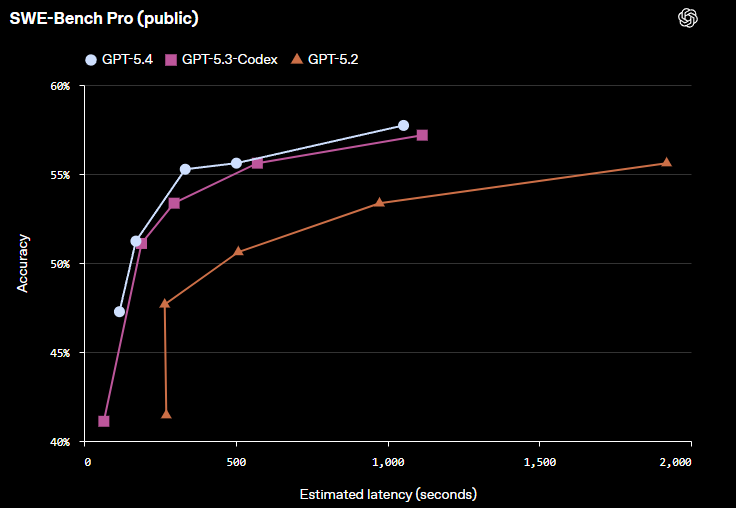
For Coding, they also shared their SWE-Bench Pro (public) Accuracy vs Latency Benchmarks:


As a demonstration of their model’s improved computer-use and coding capabilities working in tandem, they released an experimental Codex skill called “Playwright (Interactive)⁠(opens in a new window)”. This new skill “allows Codex to visually debug web and Electron apps; it can even be used to test an app it’s building, as it’s building it.”


I can’t wait to test and see how it has improved AI assisted game development!  I’ll let you know how my testing goes via my AI Assisted Unreal Engine video game development project using my Betide NeoStack AI Plugin and my OpenRouter account.

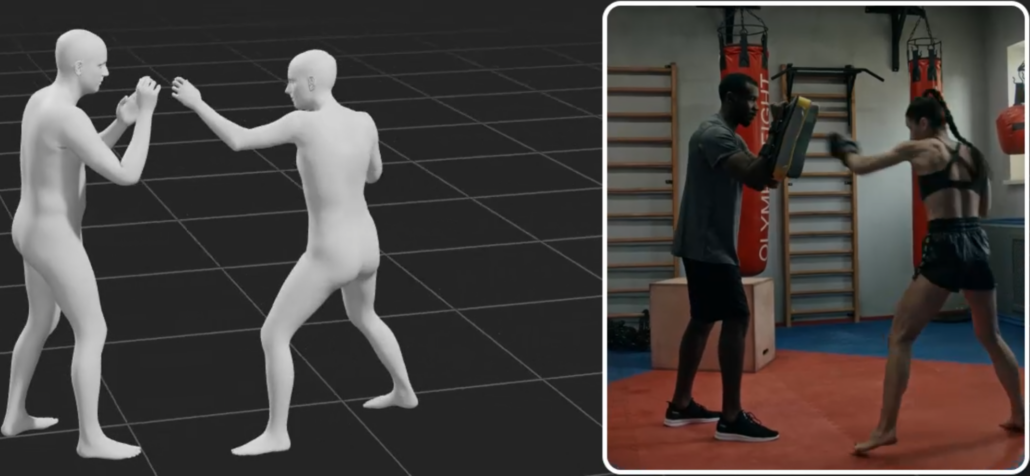
Epic Games recently acquired Meshcapade, a startup specializing in AI technologies for creating and animating hyper-realistic digital humans. Meshcapade, a spin-off from the Max Planck Institute for Intelligent Systems based in Tübingen, Germany, develops AI tools that generate precise 3D body models and animations from video recordings.

Meshcapade’s AI tools, built on the SMPL (Skinned Multi-Person Linear) parametric body model, primarily target and automate the body modeling and full-body motion capture stages in Epic’s MetaHuman pipeline, which currently relies on limited presets for bodies and less advanced video-based tracking for animation.

What Meshcapade Replaces in the current MetaHuman Pipeline:

  1. Preset/Manual Body Modeling: Replaces MetaHuman Creator’s ~50 preset bodies and external sculpting/rigging with AI-generated custom SMPL bodies from a single image, video clip, or scan. It extracts precise shape, pose, and clothing details automatically—no manual adjustments needed.
  2. Expensive Mocap Hardware: Replaces marker/suit-based systems (e.g., optical mocap studios) with markerless full-body capture from any camera (phone/webcam/pro). It tracks subtle motions like fingers/hands, camera movement, and multi-person scenes.
  3. Fragmented Body Animation: Complements/enhances MetaHuman Animator’s body solve with superior AI-driven full-body mocap, reducing retargeting hassles (pre-acquisition the plugin existed; now it will become native).

With the acquisition, Epic says it’s “looking forward to working together to advance digital human technologies for use across gaming, film and entertainment.”  I’m personally looking forward to a much simpler MetaHuman creation and animation pipeline for video game development and virtual production. development.


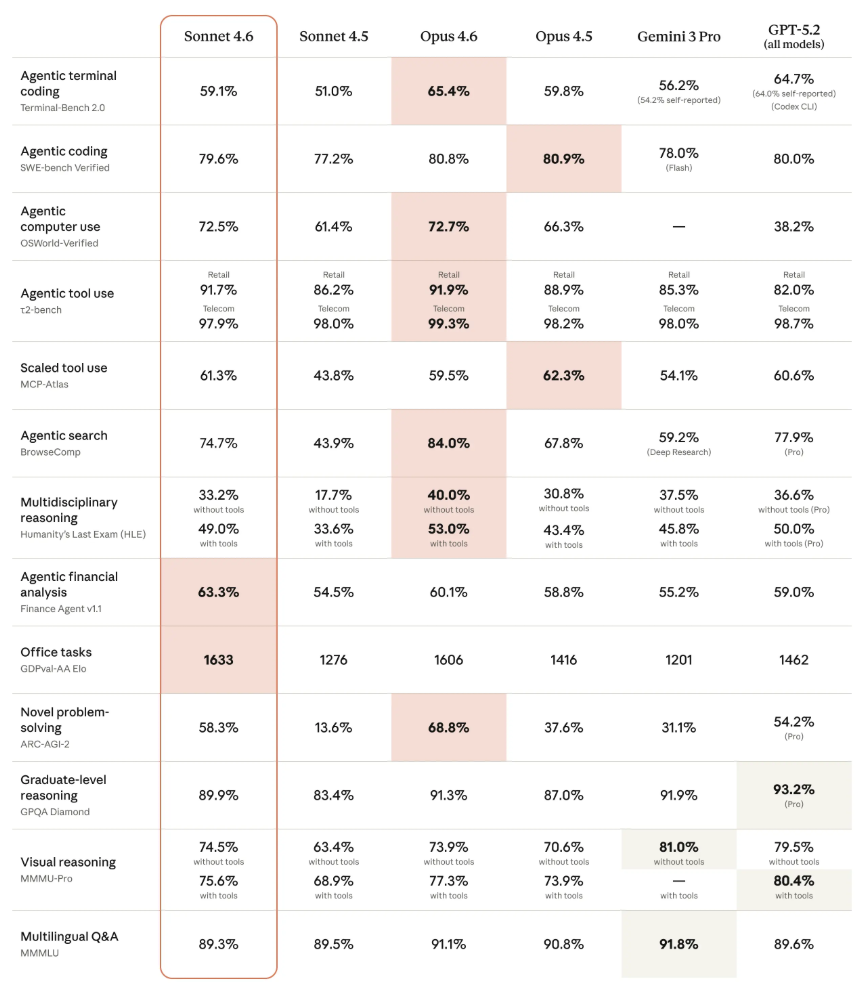
Anthropic released Claude Sonnet 4.6 on February 17, 2026 – almost 2 weeks after releasing their flagship Claude Opus 4.6 model.   Below are the latest benchmarks that Anthropic published in their Claude Sonnet 4.6 announcement:


You can read more about Anthropic Claude Sonnet 4.6 here.

In this article, I will compare two specific domains: coding an agentic application (e.g., autonomous AI agents that use tools, plan multi-step workflows, interact with environments like terminals/browsers, debug in loops, and handle real-world software engineering) and game development (e.g., designing game logic, implementing mechanics in engines like Pygame/Unity-style code, handling physics/AI/pathfinding, procedural generation, balancing systems, and iterating on prototypes).

On February 5, 2026 Anthropic released Claude Opus 4.6 which is their current flagship, optimized for the most demanding, long-horizon, and complex tasks.  On the very same day, OpenAI released GPT-5.3 Codex (the dedicated agentic coding line). GPT-5.3 Codex is OpenAI’s current flagship for advanced coding and agentic workflows.

Key Specs Comparison:

Context Window: Claude Sonnet 4.5: 200K tokens Claude Opus 4.6: 200K standard / 1M tokens (beta, with much higher reliability) GPT-5.3-Codex: Not explicitly stated in releases (likely 200K–512K range, consistent with GPT-5 family; strong on long-horizon without 1M claims yet)

Pricing (API, per million tokens) Sonnet 4.5: $3 input / $15 output Opus 4.6: $5 input / $25 output (higher beyond 200K) GPT-5.3-Codex: Similar to prior GPT-5.x tiers (~$5–15 input / $15–75 output range; exact Codex rates match high-tier GPT access via app/CLI/API)

Speed Sonnet 4.5: Fastest of the three for iteration Opus 4.6: Slower (deeper thinking/effort modes) GPT-5.3-Codex: ~25% faster than GPT-5.2-Codex; feels responsive for agent steering

Reasoning/Agent Style All three are hybrid/agentic-tuned. Opus 4.6 has adaptive effort + best long-horizon sustain. GPT-5.3-Codex emphasizes steerable, interactive agents (you guide mid-task without context loss). Sonnet 4.5 balances speed + quality.

Performance on Agentic Coding / Building Agentic Applications:

This category is extremely competitive right now — the February 5 releases were direct head-to-heads.

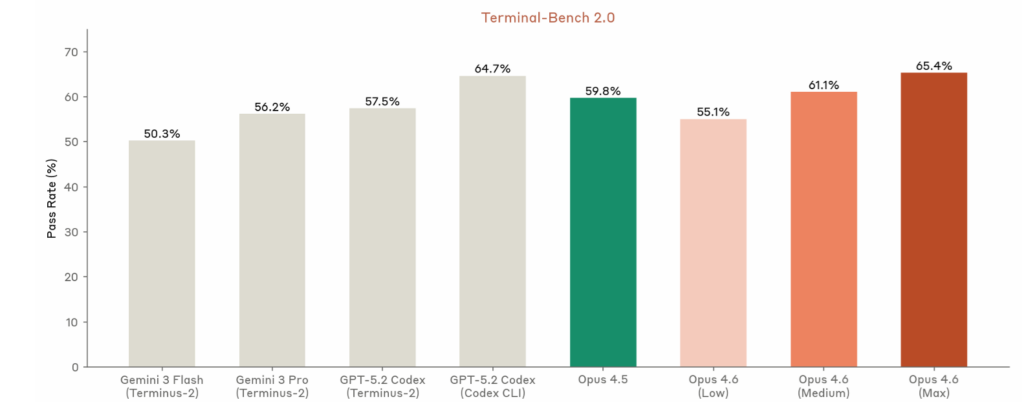
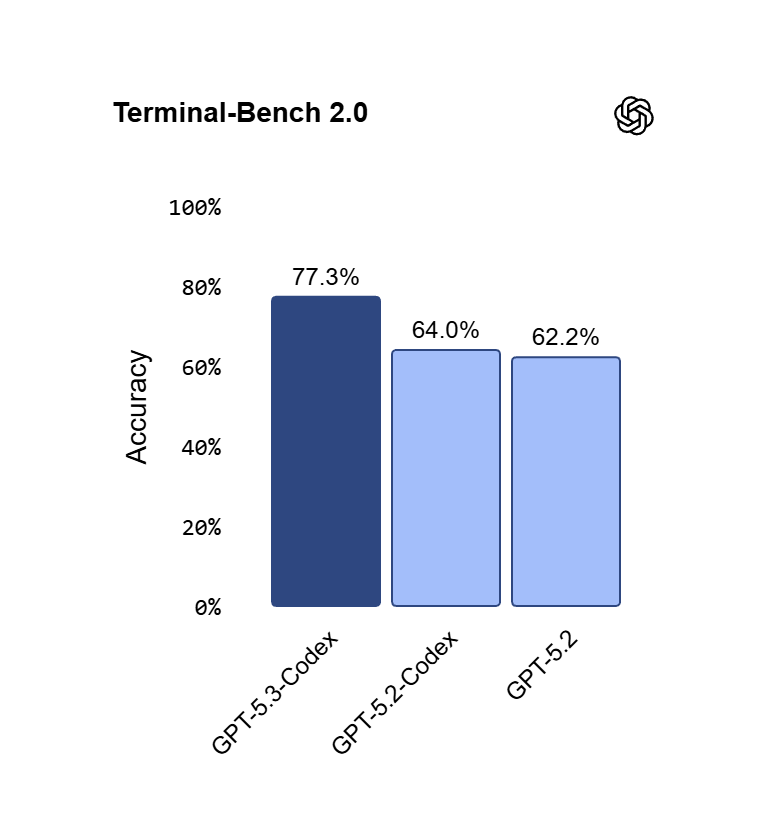
  • Terminal-Bench 2.0 (terminal/tool-use agentic coding): GPT-5.3-Codex leads at ~77.3% (state-of-the-art claim); Opus 4.6 close behind (~65–72% range in prior reports, but Anthropic claims top on agent evals); Sonnet 4.5 lower (~51%).
  • SWE-Bench Pro/Verified (real GitHub issues, multi-lang): GPT-5.3-Codex hits new highs on Pro variant (multi-lang, harder); Opus 4.6 edges on Verified for complex fixes (~80–81%); Sonnet 4.5 strong but trails slightly.
  • OSWorld / Computer Use: GPT-5.3-Codex strong (~64–65%); Opus 4.6 leads in sustained GUI/terminal chains.
  • Long-horizon Agents: Opus 4.6 excels at multi-hour autonomous runs, massive context, self-correction. GPT-5.3-Codex shines on interactive steering (like a live colleague) + tool/research chaining. Sonnet 4.5 great for volume/prototyping but needs more retries on extreme complexity.
  • Real-world vibe: Developers report GPT-5.3-Codex feels “more Claude-like” than prior OpenAI models (better git, debugging, broad tasks). Opus 4.6 often wins on deep codebase navigation + fewer hallucinations. Many use both in parallel.

Below is Anthropic’s Terminal Bench 2.0 Rating of 65.4% published by Anthropic:

Below is OpenAI’s GPT-5.3 Codex Terminal Bench 2.0 Rating of 77.3% published by OpenAI:

For serious agentic apps (autonomous tools, computer-use agents, production reliability): It’s a toss-up between Opus 4.6 (best long sustain + 1M context) and GPT-5.3-Codex (interactive steering + benchmark edges). Sonnet 4.5 is excellent but not quite frontier here.

Performance on Game Development

Game development favors creativity + systems integration + rapid iteration (mechanics, AI, procedural gen, balancing, physics sims).  All three handle Pygame prototypes, Godot/Unity pseudocode, NPC AI, etc., very well.

  • Sonnet 4.5: Best for fast prototypes/iterations — clean loops, quick balancing tweaks, simple pathfinding/behavior trees. Preferred for indie-speed work.
  • Opus 4.6: Pulls ahead on complex, interconnected systems (e.g., economy + AI opponents + physics + UI + narrative). Better at coherent large-scale design → code chains, debugging edge cases in bigger codebases, creative-yet-coherent ideas.
  • GPT-5.3-Codex: Strong contender — OpenAI highlights building “highly functional complex games and apps from scratch over days.” Excels at multi-step execution + research/tool use (e.g., pulling refs for mechanics). Feels more “productive” for iterative game workflows.

For most game prototypes/indie development: Sonnet 4.5 (speed + cost) or GPT-5.3-Codex (if you want interactive guidance).

For ambitious/systems-heavy games (e.g., simulation layers, procedural worlds, long development cycles): Opus 4.6 edges out slightly on cohesion + autonomy, but GPT-5.3-Codex is very close and often faster to iterate.

My Current Recommendation for Cloud AI Agent Assisted Development:

  • Claude Sonnet 4.5 — Default choice for 80% of agentic coding + game development: fast, cheap, reliable near-frontier.
  • Claude Opus 4.6 — Pick for the hardest agentic/long-horizon work, massive context, or when you need max reliability/cohesion (especially complex games or production agents).
  • GPT-5.3-Codex — Pick (or combine) if you value interactive steering, OpenAI ecosystem (Codex app/CLI/Copilot integration), or hit edges where OpenAI’s benchmarks shine. It’s neck-and-neck with Opus 4.6 right now — many developers test both on the same task.

I am currently using the Claude models with my OpenRouter account as I test the  Neostack AI Plugin for Unreal Game Development.

Bottom line, the AI Assisted Video Game Development race is razor-close! Real preference often comes down to workflow (e.g., Claude Code vs. Codex app), ecosystem lock-in, and the development tools for your specific game project.   In a future post, I will go over using Claude with the Unreal Engine Game and the Betide Noestack AI Plugin.